Small businesses lose hours a week to inbound mail. Not to answering it — to deciding what it is. A supplier confirming a date, an invoice, a real request for work, and forty pieces of noise wearing the same envelope.
This is the build log for an agent that does that deciding, on hardware that costs less than one month of a typical AI budget. The point of writing it down is not the machine. It is that the gap between a demo and something you can leave running is made of engineering decisions, and those are what an SME is actually buying.
The project
The agent is called apigmail. It reads inbound mail and, for each message, produces three things: what kind of message it is, what should happen to it, and how urgent it is. What needs a human gets a short summary and a proposed next action. The rest is filed, archived or binned without anyone looking at it.
It runs on a Mac mini on a shelf — 1,199 CAD, sixteen gigabytes of unified memory, bought once. No GPU rental, no per-token bill, and no mail leaving the building, the last point being the one regulated clients ask about first.
The target
Before any of it was built, the job had to be written down as something that can pass or fail. Vague ambitions cannot be engineered against; these could:
- Never bin a legitimate message. One lost customer email is worse than no automation at all, because by then the inbox is trusted.
- Never miss a message that needs a reply. Recall on that class matters more than overall accuracy.
- Decide without a human in the loop for the clear cases, and escalate the rest rather than guess.
- Run to completion overnight on hardware already owned, with no data leaving the network.
Then the measurement: two hundred synthetic business emails, written and labelled by hand, every sender and domain invented so the test set contains nobody's real mail — with about thirty deliberately hard rows: reply chains with no thread behind them, messages in French, Spanish and German, cold pitches dressed as personal notes. Every version since has been scored against that same set by macro-F1 per axis, because the classes are imbalanced and plain accuracy would flatter it. And a release has to clear a fixed gate before it ships: no more than 0.5 % invalid JSON, no more than 0.5 % legitimate mail binned, at least 0.90 recall and 0.85 precision on mail that needs a reply, at least 0.75 recall on junk. That fixture turned out to be the most valuable artefact of the project.
Fixing the measurement before the model


That is worth a paragraph because it is the most common failure in this kind of work. A week of tuning against a broken metric produces confident, measurable nonsense. Before optimising anything, confirm that the number describes what you think it describes.
What the process actually looked like
Three model builds and eight prompt versions, each scored on the same fixture. Four findings are worth passing on.
A bigger model bought nothing. The first build asked an 8B model for category, verdict and priority in one pass: excellent at spotting that a human had written, hopeless at junk — two of twenty-five junk messages caught, twenty of them marked as needing a reply. Moving to a 14B model changed the confusion pattern not at all and moved the verdict score slightly down, from 0.473 to 0.435, at two and a half seconds more per message.
Writing the rules down was worth more than the hardware. Same model, same machine: stating the decision rules explicitly — what separates an archive from a leave-alone, what makes something junk, what a newsletter pretending to be personal looks like — took the verdict score from 0.435 to 0.692.
The verdict does not belong in the model. The change that mattered most was structural. The model now only extracts observable facts: who wrote, is there a request, is there an offer, is anyone asking for a payment or a credential. Deterministic code combines those facts with context the model cannot know — prior correspondence with this sender, whether we replied, address-book membership, domains that merely resemble a known brand — and that code produces the verdict. Junk recall went from 0.24 to 0.76 with zero legitimate messages binned. The cost was honest: latency rose by about two thirds, from 12.6 to 20.6 seconds a message.
Two releases were rejected, and that is the point of the gate. A reworded prompt gained no precision and lost three points of reply-needed recall. A faster 9B build at four-bit quantisation posted the best category scores of the project and still failed, because junk recall fell to 0.60 and it binned one legitimate email. It took two further prompt versions — lookalike brands inside compound domains, fake reply chains, respecting already-read mail, leaving live threads alone — before that model was safe to ship.
The results
| Run | Build | Verdict F1 | To-reply P / R | Junk P / R | Outcome |
|---|---|---|---|---|---|
| 01 | hermes3:8b · v1 | 0.473 | 0.71 / 1.00 | 1.00 / 0.08 | baseline |
| 02 | qwen3:14b · v2 | 0.435 | 0.76 / 0.97 | 1.00 / 0.16 | bigger model, no gain |
| 03 | qwen3:14b · v3 | 0.692 | 0.78 / 0.94 | 1.00 / 0.24 | explicit rules |
| 04 | qwen3:14b · v4 | 0.835 | 0.88 / 0.96 | 1.00 / 0.76 | code decides the verdict |
| 05 | qwen3:14b · v5 | 0.838 | 0.96 / 0.90 | 1.00 / 0.72 | rejected — recall lost |
| 06 | qwen3.5:9b · v6 | 0.824 | 0.94 / 0.95 | 0.94 / 0.60 | failed — binned a real email |
| 07 | qwen3.5:9b · v7 | 0.874 | 0.96 / 0.95 | 1.00 / 0.77 | passed |
| 08 | qwen3.5:9b · v8 | 0.868 | 0.97 / 0.96 | 1.00 / 0.77 | current |
The current build runs a 9B model at four-bit quantisation, thinking disabled, an 8k context window. On the fixture it reaches 0.97 precision and 0.96 recall on mail that needs an answer, perfect precision on junk, and no legitimate message binned. In the live inbox it averages under nineteen seconds a message and sends the model about a quarter less text than the first working version did.
Capacity, since it decides whether this scales to a business. The mini answers one request at a time, so the ceiling is arithmetic: 86,400 seconds in a day divided by roughly 19 seconds a message is about 4,500 messages a day. The model is the bottleneck — not the disk, the network or the mail provider. A company taking a few hundred messages a day is using a small fraction of one desktop, and the headroom is there for the days when everyone writes at once.
And that ceiling is the floor of what budget can buy. The work is one message at a time, which makes it trivially parallel: a second 1,199-dollar machine doubles the ceiling, and nothing in the design has to change. More budget instead of more boxes buys a larger model or a longer context window on one machine, and a hosted model remains the right answer for anything a person is sitting there waiting for. The point of starting here is not that it is the limit — it is that the cheapest possible hardware already clears a small business's mail several times over, so the money can go to the parts that need judgement.
In production testingThe next improvement takes the same machine further. An email in about nine seconds instead of nineteen, and a ceiling of roughly 9,500 emails a day on one stream, 16,000 on two — on the same 1,199-dollar machine, with nothing bought.
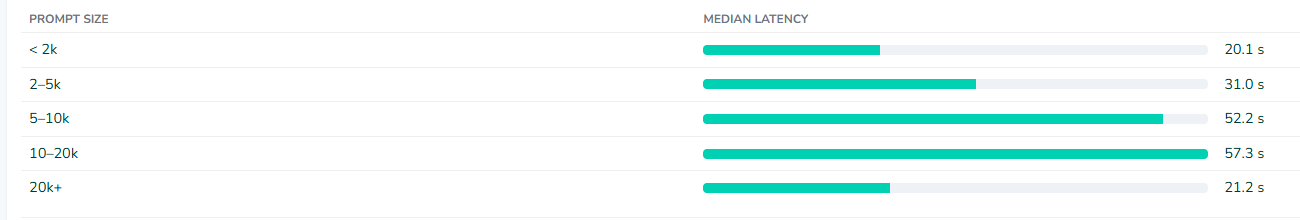
The trade-off. Shorter is faster, so nothing past 8,000 characters is read — the model gets the first 6,000 and the last 2,000, and the middle of a very long email is ignored. That is why 20k+ comes back faster than 10–20k.
One caveat stated plainly: every human confirmation collected so far was against the retired 14B build.
What this means for an SME
The hardware was never the hard part, and neither was the model. Every meaningful gain came from an engineering decision: measure properly, write the rules down, move the judgement out of the model and into code that can be tested, and keep a gate that is allowed to reject your own work.
That is exactly the kind of work two decades of building systems buys you, and it is why a small business does not need an AI budget to get something that earns its keep. A cheap desktop, an open-weights model, and someone who has done it before is a combination most SMEs can afford — and it produces a tool that runs every night, costs nothing per message, and keeps your correspondence in your own building.
If a recurring decision in your business looks like this one — high volume, clear rules, and expensive only because a person has to do it — it is worth half an hour to find out what it would take.